 Open Data Science Europe Metadata Catalog
dataset
Type of resources
Available actions
Topics
Keywords
Contact for the resource
Provided by
Years
Formats
Representation types
Update frequencies
status
Scale
Resolution
-
141: Areas with vegetation within or partly embraced by urban fabric. This class is assigned for urban greenery, which usually has recreational or ornamental character and is usually accessible for the public.
-
311: R2 of OLS regression calculated over the probabilities values (2000—2019) for broad-leaved forest.
-
131: Open-pit extraction sites of construction materials (sandpits, quarries) or other minerals (open-cast mines). Includes flooded mining pits.
-
332: Scree, cliffs, rock outcrops, including areas of active erosion, rocks and reef flats situated above the high-water mark, inland salt planes.
-
Overview: 242: Mosaic of small cultivated land parcels with different cultivation types(annual and permanent crops, as well as pastures), potentially with scattered houses or gardens. Traceability (lineage): This dataset was produced with a machine learning framework with several input datasets, specified in detail in Witjes et al., 2022 (in review, preprint available at https://doi.org/10.21203/rs.3.rs-561383/v3 ) Scientific methodology: The single-class probability layers were generated with a spatiotemporal ensemble machine learning framework detailed in Witjes et al., 2022 (in review, preprint available at https://doi.org/10.21203/rs.3.rs-561383/v3 ). The single-class uncertainty layers were calculated by taking the standard deviation of the three single-class probabilities predicted by the three components of the ensemble. The HCL (hard class) layers represents the class with the highest probability as predicted by the ensemble. Usability: The HCL layers have a decreasing average accuracy (weighted F1-score) at each subsequent level in the CLC hierarchy. These metrics are 0.83 at level 1 (5 classes):, 0.63 at level 2 (14 classes), and 0.49 at level 3 (43 classes). This means that the hard-class maps are more reliable when aggregating classes to a higher level in the hierarchy (e.g. 'Discontinuous Urban Fabric' and 'Continuous Urban Fabric' to 'Urban Fabric'). Some single-class probabilities may more closely represent actual patterns for some classes that were overshadowed by unequal sample point distributions. Users are encouraged to set their own thresholds when postprocessing these datasets to optimize the accuracy for their specific use case. Uncertainty quantification: Uncertainty is quantified by taking the standard deviation of the probabilities predicted by the three components of the spatiotemporal ensemble model. Data validation approaches: The LULC classification was validated through spatial 5-fold cross-validation as detailed in the accompanying publication. Completeness: The dataset has chunks of empty predictions in regions with complex coast lines (e.g. the Zeeland province in the Netherlands and the Mar da Palha bay area in Portugal). These are artifacts that will be avoided in subsequent versions of the LULC product. Consistency: The accuracy of the predictions was compared per year and per 30km*30km tile across europe to derive temporal and spatial consistency by calculating the standard deviation. The standard deviation of annual weighted F1-score was 0.135, while the standard deviation of weighted F1-score per tile was 0.150. This means the dataset is more consistent through time than through space: Predictions are notably less accurate along the Mediterrranean coast. The accompanying publication contains additional information and visualisations. Positional accuracy: The raster layers have a resolution of 30m, identical to that of the Landsat data cube used as input features for the machine learning framework that predicted it. Temporal accuracy: The dataset contains predictions and uncertainty layers for each year between 2000 and 2019. Thematic accuracy: The maps reproduce the Corine Land Cover classification system, a hierarchical legend that consists of 5 classes at the highest level, 14 classes at the second level, and 44 classes at the third level. Class 523: Oceans was omitted due to computational constraints.
-

Regional model ICON-D2 The DWD's ICON-D2 model is a forecast model which is operated for the very-short range up to +27 hours (+45 hours for the 03 UTC run). Due to its fine mesh size, the ICON-D2 especially provides for improved forecasts of hazardous weather conditions, e.g. weather situations with high-level moisture convection (super and multi-cell thunderstorms, squall lines, mesoscale convective complexes) and weather events that are influenced by fine-scale topographic effects (ground fog, Föhn winds, intense downslope winds, flash floods). The model area of ICON-D2 covers the whole German territory, Benelux, Switzerland, Austria and parts of the other neighbouring countries at a horizontal resolution of 2.2 km. In the vertical, the model defines 65 atmosphere levels. The fairly short forecast periods make perfect sense because of the purpose of ICON-D2 (and its small model area). Based on model runs at 00, 06, 09, 12, 15, 18 and 21 UTC, ICON-D2 provides new 27-hour forecasts every 3 hours. The model run at 03 UTC even covers a forecast period of 45 hours. The ICON-D2 forecast data for each weather element are made available in standard packages at our free DWD Open Data Server, both on a rotated grid and on a regular grid. Regional ensemble forecast model ICON-D2 EPS The ensemble forecasting system ICON-D2 EPS is based on the DWD's numerical weather forecast model ICON-D2 and currently includes 20 ensemble members. All ensemble members are calculated at the same horizontal grid spacing as the operational configuration of ICON-D2 (2.2 km). Like ICON-D2, the ICON-D2 EPS ensemble system provides forecasts up to +27 hours for the same model area (up to +45 hours based on the 03 UTC run). For generating the ensemble members, some of the features of the forecasting system are changed. The method currently used to generate the ensemble members involves varying the - lateral boundary conditions - initial state - soil moisture - and model physics. For varying the lateral boundary conditions and the initial state, forecasts from various global models are used. The ICON-D2 EPS is provided on the DWD Open Data Server in the native triangular grid. Note: All previously COSMO-D2 based aviation weather products have been migrated to ICON-D2 on 10.02.2021. However, the familiar design of these products remains unchanged.
-

Orthophotos are high-resolution, distortion-free, true-to-scale images of the earth's surface. They are produced by photogrammetric methods with the use of orientation parameters and of a digital terrain model from aerial photographs that are available as vertical images. Digital orthophotos are georeferenced. They are available for the entire area of NRW and are renewed in a 3-year cycle. They are produced according to the product standard of the Federal State, which is based on the specifications of an AdV standard (AdV (german): Arbeitsgemeinschaft der Vermessungsverwaltungen der Länder) and have a ground resolution of 10cm/pixel. They are 4-band multispectral images with a band assignment of RGBI (Red-Green-Blue-Near Infrared).
-
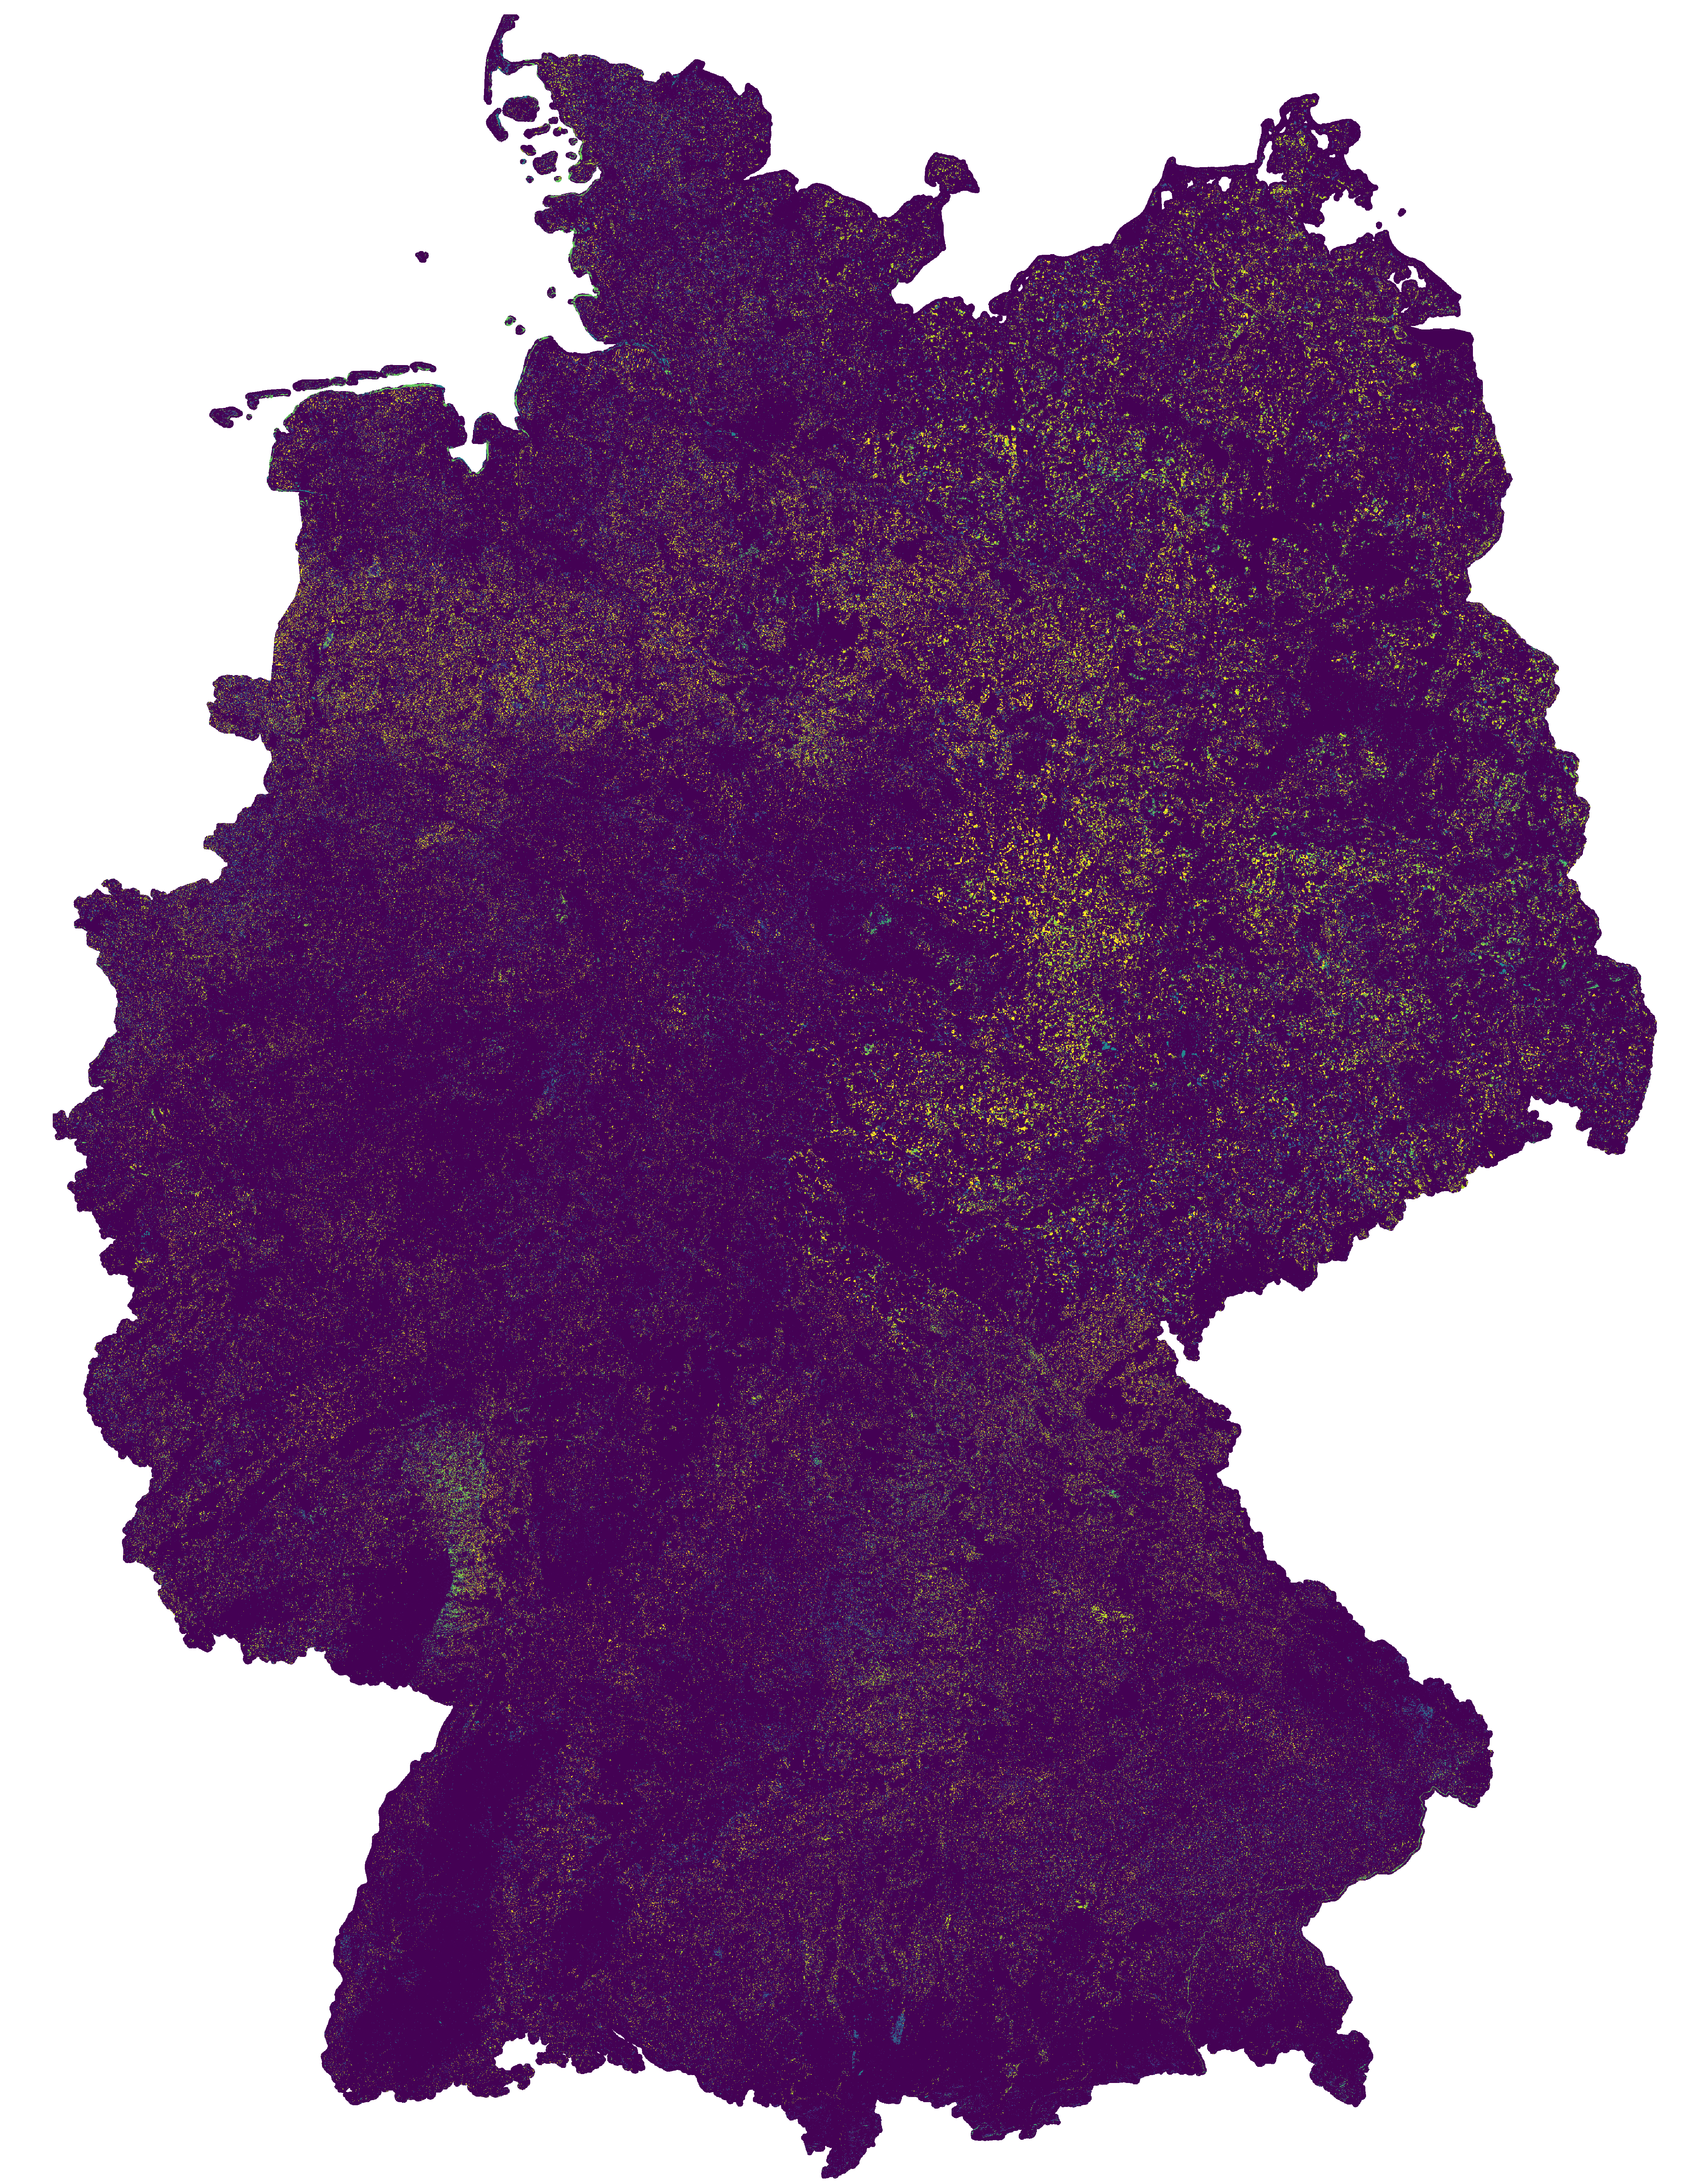
This change map was produced as an intermediate result in the course of the project incora (Inwertsetzung von Copernicus-Daten für die Raumbeobachtung, mFUND Förderkennzeichen: 19F2079C) in cooperation with ILS (Institut für Landes- und Stadtentwicklungsforschung gGmbH) and BBSR (Bundesinstitut für Bau-, Stadt- und Raumforschung) funded by BMVI (Federal Ministry of Transport and Digital Infrastructure). The goal of incora is an analysis of settlement and infrastructure dynamics in Germany based on Copernicus Sentinel data. The map indicates land cover changes between the years 2016 and 2019. It is a difference map from two classifications based on Sentinel-2 MAJA data (MAJA L3A-WASP: https://geoservice.dlr.de/web/maps/sentinel2:l3a:wasp; DLR (2019): Sentinel-2 MSI - Level 2A (MAJA-Tiles)- Germany). More information on the two basis classifications can be found here: https://data.mundialis.de/geonetwork/srv/eng/catalog.search#/metadata/db130a09-fc2e-421d-95e2-1575e7c4b45c https://data.mundialis.de/geonetwork/srv/eng/catalog.search#/metadata/36512b46-f3aa-4aa4-8281-7584ec46c813 To keep only significant changes in the change detection map, the following postprocessing steps are applied to the initial difference raster: - Modefilter (3x3) to eliminate isolated pixels and edge effects - Information gain in a 4x4 window compares class distribution within the window from the two timesteps. High values indicate that the class distribution in the window has changed, and thus a change is likely. Gain ranges from 0 to 1, all changes < 0.5 are omitted. - Change areas < 1ha are removed The resulting map has the following nomenclature: 0: No Change 1: Change from low vegetation to forest 2: Change from water to forest 3: Change from built-up to forest 4: Change from bare soil to forest 5: Change from agriculture to forest 6: Change from forest to low vegetation 7: Change from water to low vegetation 8: Change from built-up to low vegetation 9: Change from bare soil to low vegetation 10: Change from agriculture to low vegetation 11: Change from forest to water 12: Change from low vegetation to water 13: Change from built-up to water 14: Change from bare soil to water 15: Change from agriculture to water 16: Change from forest to built-up 17: Change from low vegetation to built-up 18: Change from water to built-up 19: Change from bare soil to built-up 20: Change from agriculture to built-up 21: Change from forest to bare soil 22: Change from low vegetation to bare soil 23: Change from water to bare soil 24: Change from built-up to bare soil 25: Change from agriculture to bare soil 26: Change from forest to agriculture 27: Change from low vegetation to agriculture 28: Change from water to agriculture 29: Change from built-up to agriculture 30: Change from bare soil to agriculture - Contains modified Copernicus Sentinel data (2016/2019), processed by mundialis Incora report with details on methods and results: pending
-
Overview: 241: Cultivated land parcels with a mixed coverage of non-permanent (e.g. wheat) and permanentcrops (e.g. olive trees) Traceability (lineage): This dataset was produced with a machine learning framework with several input datasets, specified in detail in Witjes et al., 2022 (in review, preprint available at https://doi.org/10.21203/rs.3.rs-561383/v3 ) Scientific methodology: The single-class probability layers were generated with a spatiotemporal ensemble machine learning framework detailed in Witjes et al., 2022 (in review, preprint available at https://doi.org/10.21203/rs.3.rs-561383/v3 ). The single-class uncertainty layers were calculated by taking the standard deviation of the three single-class probabilities predicted by the three components of the ensemble. The HCL (hard class) layers represents the class with the highest probability as predicted by the ensemble. Usability: The HCL layers have a decreasing average accuracy (weighted F1-score) at each subsequent level in the CLC hierarchy. These metrics are 0.83 at level 1 (5 classes):, 0.63 at level 2 (14 classes), and 0.49 at level 3 (43 classes). This means that the hard-class maps are more reliable when aggregating classes to a higher level in the hierarchy (e.g. 'Discontinuous Urban Fabric' and 'Continuous Urban Fabric' to 'Urban Fabric'). Some single-class probabilities may more closely represent actual patterns for some classes that were overshadowed by unequal sample point distributions. Users are encouraged to set their own thresholds when postprocessing these datasets to optimize the accuracy for their specific use case. Uncertainty quantification: Uncertainty is quantified by taking the standard deviation of the probabilities predicted by the three components of the spatiotemporal ensemble model. Data validation approaches: The LULC classification was validated through spatial 5-fold cross-validation as detailed in the accompanying publication. Completeness: The dataset has chunks of empty predictions in regions with complex coast lines (e.g. the Zeeland province in the Netherlands and the Mar da Palha bay area in Portugal). These are artifacts that will be avoided in subsequent versions of the LULC product. Consistency: The accuracy of the predictions was compared per year and per 30km*30km tile across europe to derive temporal and spatial consistency by calculating the standard deviation. The standard deviation of annual weighted F1-score was 0.135, while the standard deviation of weighted F1-score per tile was 0.150. This means the dataset is more consistent through time than through space: Predictions are notably less accurate along the Mediterrranean coast. The accompanying publication contains additional information and visualisations. Positional accuracy: The raster layers have a resolution of 30m, identical to that of the Landsat data cube used as input features for the machine learning framework that predicted it. Temporal accuracy: The dataset contains predictions and uncertainty layers for each year between 2000 and 2019. Thematic accuracy: The maps reproduce the Corine Land Cover classification system, a hierarchical legend that consists of 5 classes at the highest level, 14 classes at the second level, and 44 classes at the third level. Class 523: Oceans was omitted due to computational constraints.
-
Overview: 211: Slope of non-irrigated arable land derived by OLS regression over the probabilities values (2000—2019). The std. error of the model was considered as uncertainty. Traceability (lineage): This dataset was produced with a machine learning framework with several input datasets, specified in detail in Witjes et al., 2022 (in review, preprint available at https://doi.org/10.21203/rs.3.rs-561383/v3 ) Scientific methodology: The single-class probability layers were generated with a spatiotemporal ensemble machine learning framework detailed in Witjes et al., 2022 (in review, preprint available at https://doi.org/10.21203/rs.3.rs-561383/v3 ). The single-class uncertainty layers were calculated by taking the standard deviation of the three single-class probabilities predicted by the three components of the ensemble. The HCL (hard class) layers represents the class with the highest probability as predicted by the ensemble. Usability: The HCL layers have a decreasing average accuracy (weighted F1-score) at each subsequent level in the CLC hierarchy. These metrics are 0.83 at level 1 (5 classes):, 0.63 at level 2 (14 classes), and 0.49 at level 3 (43 classes). This means that the hard-class maps are more reliable when aggregating classes to a higher level in the hierarchy (e.g. 'Discontinuous Urban Fabric' and 'Continuous Urban Fabric' to 'Urban Fabric'). Some single-class probabilities may more closely represent actual patterns for some classes that were overshadowed by unequal sample point distributions. Users are encouraged to set their own thresholds when postprocessing these datasets to optimize the accuracy for their specific use case. Uncertainty quantification: Uncertainty is quantified by taking the standard deviation of the probabilities predicted by the three components of the spatiotemporal ensemble model. Data validation approaches: The LULC classification was validated through spatial 5-fold cross-validation as detailed in the accompanying publication. Completeness: The dataset has chunks of empty predictions in regions with complex coast lines (e.g. the Zeeland province in the Netherlands and the Mar da Palha bay area in Portugal). These are artifacts that will be avoided in subsequent versions of the LULC product. Consistency: The accuracy of the predictions was compared per year and per 30km*30km tile across europe to derive temporal and spatial consistency by calculating the standard deviation. The standard deviation of annual weighted F1-score was 0.135, while the standard deviation of weighted F1-score per tile was 0.150. This means the dataset is more consistent through time than through space: Predictions are notably less accurate along the Mediterrranean coast. The accompanying publication contains additional information and visualisations. Positional accuracy: The raster layers have a resolution of 30m, identical to that of the Landsat data cube used as input features for the machine learning framework that predicted it. Temporal accuracy: The dataset contains predictions and uncertainty layers for each year between 2000 and 2019. Thematic accuracy: The maps reproduce the Corine Land Cover classification system, a hierarchical legend that consists of 5 classes at the highest level, 14 classes at the second level, and 44 classes at the third level. Class 523: Oceans was omitted due to computational constraints.