 Open Data Science Europe Metadata Catalog
Europe
Type of resources
Available actions
Topics
Keywords
Contact for the resource
Provided by
Formats
Representation types
Update frequencies
status
Scale
Resolution
-
Areas planted with vines, vineyard parcels covering >50% and determining the land use of the area.
-
pm2.5: Monthly PM2.5 maps aggregated from the daily PM2.5 predictions.
-
Overview: Actual Natural Vegetation (ANV): probability of occurrence for the Turkey oak in its realized environment for the period 2000 - 2031 Traceability (lineage): This is an original dataset produced with a machine learning framework which used a combination of point datasets and raster datasets as inputs. Point dataset is a harmonized collection of tree occurrence data, comprising observations from National Forest Inventories (EU-Forest), GBIF and LUCAS. The complete dataset is available on Zenodo. Raster datasets used as input are: harmonized and gapfilled time series of seasonal aggregates of the Landsat GLAD ARD dataset (bands and spectral indices); monthly time series air and surface temperature and precipitation from a reprocessed version of the Copernicus ERA5 dataset; long term averages of bioclimatic variables from CHELSA, tree species distribution maps from the European Atlas of Forest Tree Species; elevation, slope and other elevation-derived metrics; long term monthly averages snow probability and long term monthly averages of cloud fraction from MODIS. For a more comprehensive list refer to Bonannella et al. (2022) (in review, preprint available at: https://doi.org/10.21203/rs.3.rs-1252972/v1). Scientific methodology: Probability and uncertainty maps were the output of a spatiotemporal ensemble machine learning framework based on stacked regularization. Three base models (random forest, gradient boosted trees and generalized linear models) were first trained on the input dataset and their predictions were used to train an additional model (logistic regression) which provided the final predictions. More details on the whole workflow are available in the listed publication. Usability: Probability maps can be used to detect potential forest degradation and compositional change across the time period analyzed. Some possible applications for these topics are explained in the listed publication. Uncertainty quantification: Uncertainty is quantified by taking the standard deviation of the probabilities predicted by the three components of the spatiotemporal ensemble model. Data validation approaches: Distribution maps were validated using a spatial 5-fold cross validation following the workflow detailed in the listed publication. Completeness: The raster files perfectly cover the entire Geo-harmonizer region as defined by the landmask raster dataset available here. Consistency: Areas which are outside of the calibration area of the point dataset (Iceland, Norway) usually have high uncertainty values. This is not only a problem of extrapolation but also of poor representation in the feature space available to the model of the conditions that are present in this countries. Positional accuracy: The rasters have a spatial resolution of 30m. Temporal accuracy: The maps cover the period 2000 - 2020, each map covers a certain number of years according to the following scheme: (1) 2000--2002, (2) 2002--2006, (3) 2006--2010, (4) 2010--2014, (5) 2014--2018 and (6) 2018--2020 Thematic accuracy: Both probability and uncertainty maps contain values from 0 to 100: in the case of probability maps, they indicate the probability of occurrence of a single individual of the target species, while uncertainty maps indicate the standard deviation of the ensemble model.
-
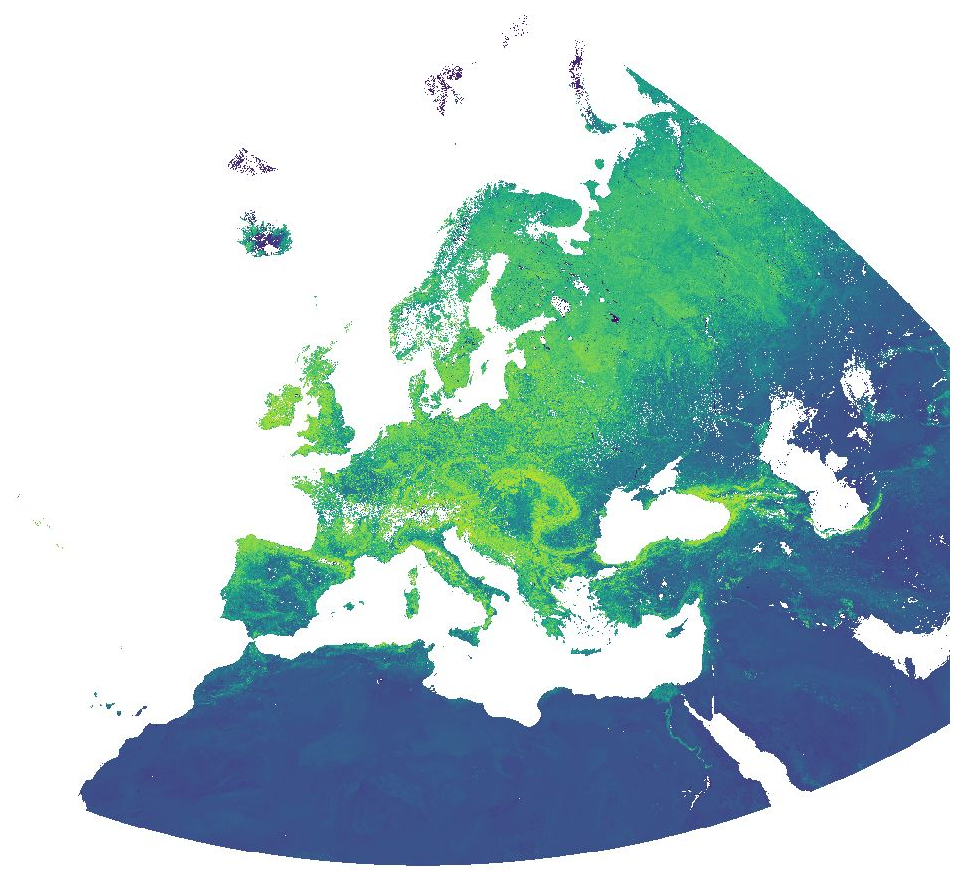
Normalized Difference Vegetation Index (NDVI) and Enhanced Vegetation Index (EVI) from MODIS data for Europe at 1 km resolution. Source data: - MODIS/Terra Vegetation Indices 16-Day L3 Global 500 m SIN Grid (MOD13A1 v006): https://lpdaac.usgs.gov/products/mod13a1v006/ - MODIS/Aqua Vegetation Indices 16-Day L3 Global 500 m SIN Grid (MYD13A1 v006): https://lpdaac.usgs.gov/products/myd13a1v006/ The MOD/MYD13A1 Version 6 product provide Vegetation Index (VI) values at a per pixel basis at 500 meter (m) spatial resolution. There are two primary vegetation layers. The first is the Normalized Difference Vegetation Index (NDVI), which is referred to as the continuity index to the existing National Oceanic and Atmospheric Administration-Advanced Very High Resolution Radiometer (NOAA-AVHRR) derived NDVI. The second vegetation layer is the Enhanced Vegetation Index (EVI), which has improved sensitivity over high biomass regions. The algorithm for this product chooses the best available pixel value from all the acquisitions from the 16 day period. The criteria used is low clouds, low view angle, and the highest NDVI/EVI value. For the time periods October 2016 - March 2017 and August 2020 - April 2021, the original data has been reprojected to ETRS89-extended / LAEA Europe and aggregated to a 1 km grid. The temporal resolution is 16 days. Bad quality pixels or pixels with snow/ice and/or cloud cover have been masked using the provided quality assurance (QA) layers and appear as "no data". File naming: productCode.acquisitionDate[A (YYYYDDD)]_mosaic_spatialResolution_frequency_VI.tif example: MOD13A1.A2020305_mosaic_1000m_16_days_NDVI.tif The date is Year and Day of Year. Values are NDVI/EVI * 10000. Example: Value 6473 = 0.6473
-
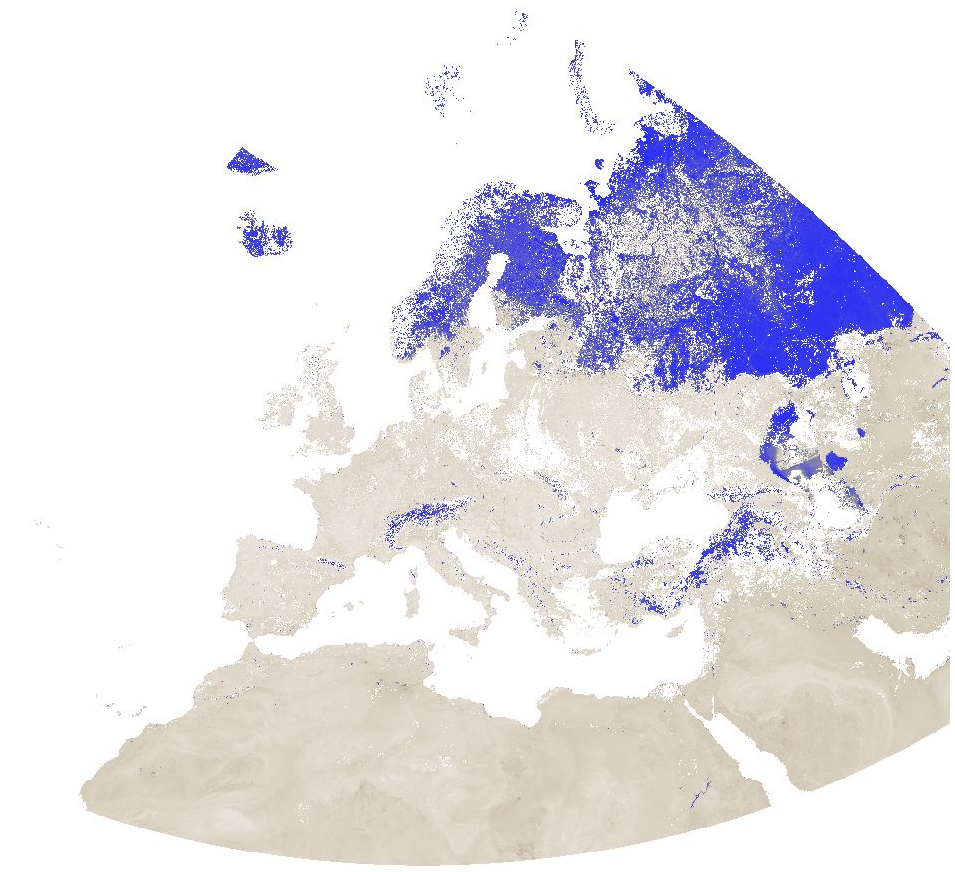
Modified Normalized Difference Water Index (MNDWI) from MODIS data for Europe at 1 km resolution. Source data: - MODIS/Terra Surface Reflectance 8-Day L3 Global 500 m SIN Grid (MOD09A1 v006): https://lpdaac.usgs.gov/products/mod09a1v006/ The corresponding MODIS/Aqua product (MYD09A1 v006) could not be used due to the fact that the Aqua satellite has a number of broken detectors resulting in unreliable data for band 6 (SWIR) measurements. The Moderate Resolution Imaging Spectroradiometer (MODIS) Terra MOD09A1 Version 6 product provides an estimate of the surface spectral reflectance of Terra MODIS Bands 1 through 7 corrected for atmospheric conditions such as gasses, aerosols, and Rayleigh scattering. Along with the seven 500 meter (m) reflectance bands are two quality layers and four observation bands. For each pixel, a value is selected from all the acquisitions within the 8-day composite period. The criteria for the pixel choice include cloud and solar zenith. When several acquisitions meet the criteria the pixel with the minimum channel 3 (blue) value is used. For the time periods October 2016 - March 2017 and August 2020 - April 2021, the original data has been reprojected to ETRS89-extended / LAEA Europe and aggregated to a 1 km grid. The temporal resolution is 8 days. Bad quality pixels (cloud, cloud shadow, dead detector, solar zenith angle too large, etc.) have been masked using the provided quality assurance (QA) layers and appear as "no data". File naming: productCode.acquisitionDate[A (YYYYDDD)]_mosaic_spatialResolution_frequency_VI.tif example: MOD09A1.A2016353_mosaic_1000m_8_days_MNDWI.tif The date is Year and Day of Year. Values are MNDWI * 10000. Example: Value -5099 = -0.5099
-

The Land Cover Map of Europe 2017 is a product resulting from the Phase 2 of the S2GLC project. The final map has been produced on the CREODIAS platform with algorithms and software developed by CBK PAN. Classification of over 15 000 Sentinel-2 images required high level of automation that was assured by the developed software. The legend of the resulting Land Cover Map of Europe 2017 consists of 13 land cover classes. The pixel size of the map equals 10 m, which corresponds to the highest spatial resolution of Sentinel-2 imagery. Its overall accuracy was estimated to be at the level of 86% using approximately 52 000 validation samples distributed across Europe. Related publication: https://doi.org/10.3390/rs12213523
-
Overview: Actual Natural Vegetation (ANV): probability of occurrence for the Sweet chestnut in its realized environment for the period 2000 - 2021 Traceability (lineage): This is an original dataset produced with a machine learning framework which used a combination of point datasets and raster datasets as inputs. Point dataset is a harmonized collection of tree occurrence data, comprising observations from National Forest Inventories (EU-Forest), GBIF and LUCAS. The complete dataset is available on Zenodo. Raster datasets used as input are: harmonized and gapfilled time series of seasonal aggregates of the Landsat GLAD ARD dataset (bands and spectral indices); monthly time series air and surface temperature and precipitation from a reprocessed version of the Copernicus ERA5 dataset; long term averages of bioclimatic variables from CHELSA, tree species distribution maps from the European Atlas of Forest Tree Species; elevation, slope and other elevation-derived metrics; long term monthly averages snow probability and long term monthly averages of cloud fraction from MODIS. For a more comprehensive list refer to Bonannella et al. (2022) (in review, preprint available at: https://doi.org/10.21203/rs.3.rs-1252972/v1). Scientific methodology: Probability and uncertainty maps were the output of a spatiotemporal ensemble machine learning framework based on stacked regularization. Three base models (random forest, gradient boosted trees and generalized linear models) were first trained on the input dataset and their predictions were used to train an additional model (logistic regression) which provided the final predictions. More details on the whole workflow are available in the listed publication. Usability: Probability maps can be used to detect potential forest degradation and compositional change across the time period analyzed. Some possible applications for these topics are explained in the listed publication. Uncertainty quantification: Uncertainty is quantified by taking the standard deviation of the probabilities predicted by the three components of the spatiotemporal ensemble model. Data validation approaches: Distribution maps were validated using a spatial 5-fold cross validation following the workflow detailed in the listed publication. Completeness: The raster files perfectly cover the entire Geo-harmonizer region as defined by the landmask raster dataset available here. Consistency: Areas which are outside of the calibration area of the point dataset (Iceland, Norway) usually have high uncertainty values. This is not only a problem of extrapolation but also of poor representation in the feature space available to the model of the conditions that are present in this countries. Positional accuracy: The rasters have a spatial resolution of 30m. Temporal accuracy: The maps cover the period 2000 - 2020, each map covers a certain number of years according to the following scheme: (1) 2000--2002, (2) 2002--2006, (3) 2006--2010, (4) 2010--2014, (5) 2014--2018 and (6) 2018--2020 Thematic accuracy: Both probability and uncertainty maps contain values from 0 to 100: in the case of probability maps, they indicate the probability of occurrence of a single individual of the target species, while uncertainty maps indicate the standard deviation of the ensemble model.
-
Overview: 312: Vegetation formation composed principally of trees, including shrub and bush understorey, where coniferous species predominate. The predominant classifying parameter for this class is a crown cover density of > 30 % or a minimum 500 subjects/ha density, with coniferous trees representing > 75 % of the formation. The minimum tree height is 5 m (with the exception of Christmas tree plantations). Traceability (lineage): This dataset was produced with a machine learning framework with several input datasets, specified in detail in Witjes et al., 2022 (in review, preprint available at https://doi.org/10.21203/rs.3.rs-561383/v3 ) Scientific methodology: The single-class probability layers were generated with a spatiotemporal ensemble machine learning framework detailed in Witjes et al., 2022 (in review, preprint available at https://doi.org/10.21203/rs.3.rs-561383/v3 ). The single-class uncertainty layers were calculated by taking the standard deviation of the three single-class probabilities predicted by the three components of the ensemble. The HCL (hard class) layers represents the class with the highest probability as predicted by the ensemble. Usability: The HCL layers have a decreasing average accuracy (weighted F1-score) at each subsequent level in the CLC hierarchy. These metrics are 0.83 at level 1 (5 classes):, 0.63 at level 2 (14 classes), and 0.49 at level 3 (43 classes). This means that the hard-class maps are more reliable when aggregating classes to a higher level in the hierarchy (e.g. 'Discontinuous Urban Fabric' and 'Continuous Urban Fabric' to 'Urban Fabric'). Some single-class probabilities may more closely represent actual patterns for some classes that were overshadowed by unequal sample point distributions. Users are encouraged to set their own thresholds when postprocessing these datasets to optimize the accuracy for their specific use case. Uncertainty quantification: Uncertainty is quantified by taking the standard deviation of the probabilities predicted by the three components of the spatiotemporal ensemble model. Data validation approaches: The LULC classification was validated through spatial 5-fold cross-validation as detailed in the accompanying publication. Completeness: The dataset has chunks of empty predictions in regions with complex coast lines (e.g. the Zeeland province in the Netherlands and the Mar da Palha bay area in Portugal). These are artifacts that will be avoided in subsequent versions of the LULC product. Consistency: The accuracy of the predictions was compared per year and per 30km*30km tile across europe to derive temporal and spatial consistency by calculating the standard deviation. The standard deviation of annual weighted F1-score was 0.135, while the standard deviation of weighted F1-score per tile was 0.150. This means the dataset is more consistent through time than through space: Predictions are notably less accurate along the Mediterrranean coast. The accompanying publication contains additional information and visualisations. Positional accuracy: The raster layers have a resolution of 30m, identical to that of the Landsat data cube used as input features for the machine learning framework that predicted it. Temporal accuracy: The dataset contains predictions and uncertainty layers for each year between 2000 and 2019. Thematic accuracy: The maps reproduce the Corine Land Cover classification system, a hierarchical legend that consists of 5 classes at the highest level, 14 classes at the second level, and 44 classes at the third level. Class 523: Oceans was omitted due to computational constraints.
-
421: Vegetated low-lying areas in the coastal zone, above the high-tide line, susceptible to flooding by seawater. Often in the process of being filled in by coastal mud and sand sediments, gradually being colonized by halophilic plants. Salt marshes are in most cases directly connected to intertidal areas and may successively develop from them in the long-term. Salt-pans for extraction of salt from salt water by evaporation, active or in process of abandonment. Sections of salt marsh exploited for the production of salt, clearly distinguishable from the rest of the marsh by their parcellation and embankment systems. Coastal zone under tidal influence between open sea and land, which is flooded by sea water regularly twice a day in a ca. 12 hours cycle. Area between the average lowest and highest sea water level at low tide and high tide. Generally non-vegetated expanses of mud, sand or rock lying between high and low water marks. The seaward boundary of intertidal flats may underlay constant change in geographical extent due to littoral morphodynamics. Range of water level between low tide and high tide may vary between decimeters and several meters in height.
-
223: Cultivated areas planted with olive trees.